Grok 4.7
x.ai408 points by meetpateltech 5 hours ago
408 points by meetpateltech 5 hours ago
Apparently Grok 4.7 has 40% more weights than Grok 4.6, but the price ($6 output token, $2 input) is the same.
Given that the decrease in their margin and the fact they delayed the release of Grok 4.7 almost two weeks past the original date, XAI must not have been happy with the results for 4.7. And XAI also waited the day before Opus 5.5 is rumored to launch. I imagine Opus 5.5 will blow Grok 4.7 out of the water benchmark wise.
However, I have become skeptical of benchmarks. Grok 4.5 solved some issues setting up a buildroot system that Fable 5 couldn't do. I find the post cursor groks are phenomenal at frontend web development, though Claude is much better at backend ruby.
My favorite part of the new Groks has been how they speak in plain english. I simply cannot stand Claudish. Or even GPT, which doesn't have Claude's ticks but definitely likes to handwave explaining technical concepts. Still, nothing beats Claude 3.5 and 4 with explaining since it seems all models have regressed. I wonder if Grok 4.7 will also regress with English because of all the RL.
FYI a quick fix for claudish is to ask for the response to be in ASD-STE100 (Simple Technical English). Then it is far more readable. But I would agree that this is an annoyance and shouldn't require user workaround to get something readable.
I think this is more a meme than anything else, for a couple reasons:
First, after a while it's just as grating as Claudeish. Second, my hunch is that it constricts the actual thinking of the LLM, like the same way that Newspeak does in 1984. It shrinks the range of thought that can be expressed if used as an input.
I think the real way to do it is to have another Claude entirely deal with the user as a liaison, but to keep the thinking in whatever format it came in.
Latent space reasoning, if you think about it, is exactly this to a crazy degree: why even formulate a thought as words if you can just keep it as matmuls until the user needs it? And then, if the user needs it, have it always specifically formulated for the user by another LLM rather than constrict its range of thought? Anyway, that's my take.
The fact that it might affect quality is something that is on my mind. In fact, I have mainly been using Astra after being primarily on Claude for several years exactly because of this annoyance. Ultimately, the model (at least for coding purposes) should just... not have this writing style.
I do think an infrastructure where another Claude retranslates the output would be better. Oftentimes I forget to put it in the actual prompt and when I receive back 8 paragraphs of Claudeish I ask for it then.
I would have to disagree that it gets as grating as Claudeish though. Its just direct and professional instead of ring-around-the-rosy clickbait.
This is the same reason why I am a bit skeptical of LLM superintelligence. LLMs in the end have to operate in natural language concepts and the complexity of natural language is bounded by limits of human cognition. I'm sure super advanced AI could use concepts that humans not only have no words for, but might not be able to understand alltogether. As such if my thesis is correct, the only way forward for true superintelligence may be getting rid of natural language COTs.
There are two separate questions, right?
1. Is natural language holding LLMs back by some %? 2. Is natural language serving as a hard gate that will prevent LLM intelligent progressing past some specific point?
The answer to 1 seems like an obvious yes to me.
Your thesis says the answer to 2 is "yes." That doesn't feel right to me. Think about all of the humans who have pushed various fields forward: Einstein, Newtown, Bach, whoever. If natural language doesn't prevent an entity from surpassing humans in one intellectual field, why would it prevent an entity from surpassing humans in all intellectual fields?
(To be clear, I'm not claiming superintelligence will or won't be achieved; I'm considering your specific thesis about whether or not natural language will be a hard gate)
> LLMs in the end have to operate in natural language concepts and the complexity of natural language is bounded by limits of human cognition.
I don't think this is true.
They have to express themselves as tokens. The meaning of those tokens doesn't have to be text. See any model that can handle images/video. Also, I don't think math, svg, etc, are "natural" language.
And, only the final expression is tokens. The intermediate layers, with the encoded concepts, aren't "natural language".
But, to address your concern (which nobody can disagree with, since even humans can't fully express through text/pictures), potentially: https://news.ycombinator.com/item?id=49758615
Yeah, as I understand it, natural language is tokenised and vectorised, and then maths takes ahold.
The model isn't limited to concepts that can be expressed in natural language.
It's only once the AI gets to the output layers that natural language comes back into play.
After all, they're all made out of weights[0].
Each letter has it's own token. LLMs can invent new words if they want to, just like humans do. All the fancy words we use today in science did not exist even 100 years ago. And that didn't stop us.
How would this word inventing thing work? And how useful would it be? Can we make a POC around this?
Ask for output to the user in "simple technical English", let it think how it wants. It is hard to believe all the flowery prose is actually helpful to the model.
A few weeks ago two "Claude wrapper" projects showed up here within 24 hours of each other. Both seemed to just sand the details away--useful if Claude is too wordy, I suppose, but seemed to also lose real substance.
Does not work for Claude, at least for me and I put it as the system prompt
For me it works at first but Claude models forgets it after some prompts, despite only using like 100k tokens.
Your best bet is to use hooks and inject it after every file edit / response by first running the content through haiku and asking if it is asd 100 ste.
It burns more tokens but is the only way to get tolerable text.
Doesn't it just get attenuated and start ignoring those commands?
The hook sends the text to another agent/context with a request to validate and return a good or bad + reason response. Every request is a fresh context.
I don’t think system prompts are particularly reliable way to do much at all. It’s better to put it as a hook after each response, or a skill at least so you can trigger it at will if you don’t want it everytime.
Do you think they're unreliable based on the position in the conversation or other factors?
Anthropic has probably RL’d the system prompt into nothing because of their fear of the user being able to control the model. If it listened to you about the slop language, it might listen to you if you asked it to help you with no-no tasks.
It does work, you however have to put it into every single prompt in which you didn't want a rubbish response
Literally every one, even 1-2 prompts later it starts to go back
I tell mine to address me as a tech priest of the adeptus mechanicus. Works great.
I created a custom output style based on this (borrowing some from github.com/AminBlg/SimpleEnglish) and I've found it to be better than the default or concise output styles, but still not as good for me as current GPT or Gemini models when it comes to communicating.
I tried this a while back and I felt like the result was the same weird shoehorning of ideas into language, just with a different vocabulary. I’d really like for it to work, though.
I put this rule in my CLAUDE.md: "Always write a TLDR in layman terms", it seems to do the trick
For what it's worth - over the last few years or whatever, it seems like Anthropic benchmaxxes the least.
That being said, I currently prefer Sol / Astra to Opus / Fable as I find both to be a better cost payoff to me.
I was going to say the reverse - claude has been the less satisfying normalized by benchmark for me in the last year. Both astra and fable have their quirks, but I am 90% codex this year up from 10% last year.
I've been getting a ton done with Fable as the supervisor and astra as the implementer, with opus for adversarial reviews of the astra PRs. You can use terminal multiplexers with custom harnesses to allow Fable to start codex sessions and send instructions / read instructions / allow/deny actions. It's pretty cool!
It's not just about benchmaxxing. Sincerely targeting those long-autonomy benchmarks is questionable in the first place, because naturally it drives the model to assume more and more about what you want.
The target market for frontier models is CEOs who want to lay off entire departments of their company. So the long autonomy benchmarks would seem to be sending exactly the right signal.
They're still going to have to communicate with the bots replacing those departments they lay off, or they're going to have a bad time.
> I simply cannot stand Claudish
I totally agree, it’s like that as models become more intelligent, they are less understandable by most of people... but aren’t we humans doing the same?
Agreed. The more knowledge you amass on a subject, the more important it becomes to be extremely specific and nuanced - or your communications end up being incorrect. You become better at expressing your thoughts, but harder to understand.
The weird thing is, that's not what AI models seem to be doing. The prose is just weird.
> You become better at expressing your thoughts, but harder to understand.
This happens most though when the speaker doesn't (or care to) understand their audience.
Eg i find effective communication requires expertise in both the subject matter domain but also the reference of the listener. Eg in ELI5 framing, if you don't know what information 5yr olds are expected to know you'll do a poor job at an ELI5.
It often feels like Claude does poorly at both framing the response relative to what it "thinks" the listener knows, but also the prose is... sideways, just weird as you said.
I find people tend to lack nuance in their communication more often - leading to problems and misunderstandings.
If I don't grok an elaborate explanation, I can ask for clarification. If it's explained to me in an overly simplistic or unnuanced way, I'll walk away with a false sense of understanding.
That said, I'm sure we all have very different concentrations of these types of people and problems around us. I've definitely met some engineers who seem to actively try to make their language incomprehensible
I'm going to assume it's very difficult to assume what a user actually knows from the very small signal that comes in a prompt.
effective communication is knowing who the audience is. Everyone naturally knows their audience to some extent, except for the "neuro-atypicals".
It is unsurprising that a LLM fails, without coaching, to effectively communicate.
> The prose is just weird.
Agreed. Do you think it's due to that EU issue of making AI text be identifiable?
That went into effect a month ago. Claude prose quality has been a disaster at least since Opus 4.7
They’re training the models on generated slop. I’ve done a comparison on samples from the different versions of Claude and they’re worlds apart. The ancient, supposedly obsolete models speak normal English.
That's half true. A very smart model should be able make good explanations, which include simple understandable prose. That can should be possible even as its thought process gets more alien.
The best ideas are usually the simplest to elaborate. If someone comes up with a convoluted scheme that are hard to understand or be adequately explained, it's usually fraud.
When claude speak in convoluted mess, they are often going off on tangents in real work that you asked it to do, too.
That believes that the world can be simplified into dichotomies, or at least, simplified. Sometimes problems are complex, and the solutions to them necessarily so. For example, cancer. I order to begin to understand that problem, you have to understand the utter complex scheme it has devised in order to exist. A 20 minute YouTube video isn't going to be able to begin to cover the basics of the subject, although there are some good ones, with clever analogies.
Just because something is difficult to understand doesn't mean it's fraud, although if someone is trying to dazzle you with clever words and names of institutions you recognize because they are selling you something, there's a good chance they're lying to you in order to get some money from you.
No but almost all good ideas can be reduced down to a few sentences if you're good at explaining things. It's a different kind of intelligence than what's commonly called IQ but it's something like that regardless.
Sure the explanation will oversimplify a lot but then you can expand it recursively if needed, you gotta start somewhere.
> That believes that the world can be simplified into dichotomies, or at least, simplified. Sometimes problems are complex, and the solutions to them necessarily so. For example, cancer
You just simplified most of the problems people work on down to cancer complexity. Ironic, isn't it?
That's also simply not the case, most people are building CRUD apps with some frontend code and some accessory stuff like build systems etc., which while complex, can still be expressed in very plain, easy to understand language for anyone who's a bit technical.
Does not excuse the Claude slop.
If you are saying that there are problems more complex in this world than cancer to be solved, I'm not denying you.
Solving the problem right in front of you is easy. Stepping back and asking: is that a problem to be solved, is infinitely harder.
I did not use Claude to write my comment, so I don't know where that is coming from.
I meant the explanation does not excuse Claude's slop prose, not your comment.
What I notice about Claudish is that it has its preferred cliche’s and overstretched methaphores, it packs too many ideas in a sentence, and to achieve the latter it makes up adjectives.
I should try adding these tips to my system prompt. Is there a shorthand to describe such language use? I am not a native English speaker.
Look up the output-style setting, which is a bit stronger than putting it in the system prompt. The new "concise" setting is better than the default but in practice, Claude is a very stubborn model when it comes to these patterns and they're really hard to eliminate, mostly you can only hope to mitigate.
As for the wording of the prompt, you're pretty on point, I created a custom output style targeting mostly the first two you have there. Some people have wording that demands a certain technical standard or uses fancy words to describe what to avoid, but I haven't seen evidence those work better than asking plainly and I suspect the opposite: LLMs mimic the user to a degree so talking to it in terms of technical specifications and fancy words is an invitation to get them back.
Yeah just today it told me in a snarky way that my CPU (7940HX) doesn't exist and that I must have misread it and it's either 7945HX or 7940HS. Yes, AMD (re-)branding CPU models makes things difficult but I thought we are past AI models making such egregious mistakes
This is /r/iamverysmart material (by Claude)
Part of intelligence is knowing your audience and communicating efficiently.
> Part of intelligence is knowing your audience and communicating efficiently.
Bingo! And on this axis many SOTA models fail miserably. These things are acting on my behalf under my direction. All the supposed intelligence in the world means fuck-all if nobody can understand it.
And like somebody else said… when meat-based humans talk like Claude does, it almost always means they either don’t understand what they are talking about, or are actively trying to conceal something and are a fraud. Not always, but almost always.
Perhaps you haven't had the chance to use it, but 3.8 flash is the best model for talking too. Even routing Claudes output through 3.8 to have it explain whats going on is a breath of fresh air
Agreed. It's very capable for something carrying the "flash" label, super fast, and very clear to read.
I'll have to try Gemini Flash for coding. The reason I haven't I used Gemini for coding is last time I tried it couldn't call tools very well.
I am a huge fan of Gemini Pro for chat... gemini somehow just knows the most obscure stuff. I'll double check something Gemini said and find the source is deep inside a hard to access scientific paper. Google just has the best index of the internet.
I remember the Gemini 2.5 Pro series was the best at text, but failed half of it's tool calls. They really redeemed themselves with the 3.5 Flash series, it's great. I love how fast it is. Now if only they could offer a subscription service for it...
Makes sense. When Google Jules was new, I experimented with it for a while and it was embarrassing how often it flubbed tool calls, often repeatedly. It tended to forget the working directory so almost every command needed two tries.
It's coding is still meh. Greenfield applets all day, but don't throw it in the jungle.
It's best for brain storming, rabbit holes, and image recognition.
Let the big models do the heavy lifting for now.
Agreed.
Even if you aren't coding, you really need to double check its answers. Flash 3.8 hallucinated a Keyence camera's max operating temperature for me, last week, and backed it up with "references".
It's still my favorite model for most non-coding stuff, though.
I would if they let me bring the subscription I have to the harness of my choice.
> Claudish
I do wonder why a frontier model does this to be honest. It still does good coding wise, but it seems strange to me. r/Claude is full of "load bearing" jokes in every thread.
I've found grok 4.6 speaks heavily in Claudish. It especially likes using verbs as nouns.
$0.50 for cache reads, which is 25% of input. While other models are 10% of input.
And like that grok4.7 cache reads are more expensive than sol's (at $0.40/mil).
Token price doesn't tell you much without knowing token efficiency.
Their leading benchmark with cost per task shows a tough sell compared to Fable 5.1 Low and doesn't reach the performance of Fable 5.1 Medium.
How representative that is of real world usage, I don't know.
In their benchmark GPT 5.6 Sol performs suspiciously poorly compared to the former models.
> I find the post cursor groks are phenomenal at frontend web development, though Claude is much better at backend ruby.
Wonder if we'd benefit from a much more specialized + task-specific benchmarks to paint a clearer picture like this. A benchmark solely for frontend, ruby, hardware, etc.
Agreed, Claude has a "Claude Design" tool but doesn't publish any frontend brenchmarks. Maybe the industry will develop one.
> My favorite part of the new Groks has been how they speak in plain english.
I don't know if it's the plain english or what, but I really like Grok for legal research (as opposed to code). It's got a noticeable edge in getting to the point compared to Opus 5.
For me Grok finds legit bug that Fable and Astra miss so I always run it as part of code review
I've noticed Chatgpt 5.6 Sol High, on the chat interface, inventing words that are a mixture of Portuguese and English. Like "hardcodar" a mix of "hardcode" and the most common verb ending in Portuguese "-ar". Some don't have a single google hit
Do you have any connection to Portugal? I imagine if you have Portuguese in any of your prompts that might bleed into your user profile which becomes a part of every prompt. Alternatively it might use browser language settings
Using a variety of models feels similar to the benefit of having a team of individuals from different backgrounds.
I expect the next Anthropic release to finally reduce the prevalence of Claudish
If they fix Claudish, they've earned me back as a max customer!
Fable 5.1 is not there quite there yet.
They need to get that Sonnet 3.5 magic back.
Same. The issue with Anthropics models is that (speaking regarding code generation) they REFUSE any kind of comment override instructions. I've tried everything and no matter what, after a few turns, they resort to generating the same overtly verbose junk. Bun's codebase is littered with them See
   // `HANDLE` is an opaque kernel handle (kernel32 validates and returns 0/FALSE
   // on a non-console handle); every out-param is `&mut T` to a `#[repr(C)]` POD,
   // ABI-identical to the Win32 `LP*` pointer (thin non-null). The reference type
   // encodes the only pointer-validity precondition, so `safe fn` discharges the
   // link-time proof. (`bun_windows_sys::kernel32` declares these with `*mut`;
   // redeclared locally so the legacy-conhost cursor path below is plain calls.)
   // Progress's terminal handle is the canonical `output::File` (vtable-backed
   // stderr/File from `OutputSinkVTable`). The duplicate `ProgressTerminalVTable`
   // from B-0 round 1 is removed; tty/ansi/winsize route through    the new
   // `OutputSinkVTable` slots so `bun_core` stays T0 (no `bun_sys` dep).
Based on?
It's pretty much the biggest complaint of Claude compared to its competitors, so they really should adress it .
Based on not being an idiot. Simple observation is enough.
I asked, where is the evidence that they're going to fix it? We all know its shit.
Grok and Zai have both been excellent as adjunct code-reviews, on their cheapest plans, for me. Fable plans, Opus writes, Codex as primary reviewer, but Grok and Zai usually find something worth fixing that the others have missed. Both are well worth whatever the $20 or so I'm paying for them
it's definitely not bigger. smaller if anything looking at how much faster it is
I do not understand how anyone can seriously use a tool that has "Be funny and irreverent when appropriate" baked into the system prompt.
I don't want to waste money because my calculator is cracking jokes. They don't deserve their paltry 5% marketshare or whatever it is they have currently. I'm not even getting into Musk as a person or the horrid things we've seen Grok spit out on twitter. I just don't trust his companies with my data and I have seen very little evidence that it's ever the best tool for the job. I'm sure those cases exist but I can't imagine it's worth it.
I am on the exact same page as you, but there is definitely a market for LLMs which speak more conversationally and less like Claude! Non-programming use cases abound and most users don't like the rigid, exact tone that engineering demands.
Why are they comparing grok 4.7 xhigh to grok 4.6 high?
Unless they produce the same token output on the face of it, it looks like they're trying to cover for 4.7 not having good model perf?
Nice to see this release cadence increasing and some continued improvement in quality. I am guessing these models are basically still outcomes of the cursor team integrating with the massive amount of compute they now own: I’d imagine we will see significant step up improvements with grok 5 later this year as the team gets more experienced and confident with larger training deployments. Here’s hoping for another competitive frontier model!
https://tools.simonwillison.net/markdown-svg-renderer?url=ht... - default reasoning level.
Here's reasoning level high: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
For some reason reasoning effort low and medium used similar numbers of tokens, and xhigh used less than high. I think I need to try without OpenRouter in the middle.
UPDATE: I tried again with the xAI API directly: https://tools.simonwillison.net/markdown-svg-renderer?url=ht... - not a great deal of difference between reasoning levels, and this time xhigh and low used the same number of reasoning tokens for some reason.
For comparison here's a fresh run against Grok 4.6: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
I think these are the worst I've seen, at least in some time. It's a silly benchmark though, not sure what to make of it
I think the result is fine. The benchmark is silly to the point of being useless nowadays.
It used to be a mess in various interesting ways. Now, almost every big release can draw something perfectly functional.
So the question - without a correct answer - given the prompt "Generate an SVG of a pelican riding a bicycle":
Does the user want the least lines of code to make it functional, or the best looking version?
I tried in Cursor and see a lot of improvements over Grok 4.6 svgs. The AA numbers indicate it's not very token efficient though: https://artificialanalysis.ai/agents/coding-agents?agents=co...
Poor fella doesn’t have a seat. Intriguing design where both pedals are on the same side of the frame. Balancing must be a challenge.
Are there good tools for doing context audits? I feel I have no good way to visualize what a new session is getting by default in a given repo without crawling through every potentially included markdown file
Hahaha. I remember when musk and his merry band of sycophants were bragging about grok producing the only physically accurate bicycle. What happened?
Yeah, he had opinions: https://twitter.com/elonmusk/status/2023833496804839808
It's definitely gotten better at image->html workflows. Here's a test comparing Astra (currently SOTA at this) vs Grok 4.7:
Designs: https://image.non.io/78795662-8bfc-4e14-8d72-3738392aa6b3.we...
Astra's build: https://html.non.io/annui/
Grok's build: https://html.non.io/Annui-grok/
Additional prompt instructions: "Add scrolling clouds behind the statues. Dynamically light the statues based on mouse position. Use diffui to generate the normal maps/depth maps/roughness maps of the objects, and to separate out the assets on to different layers."
Overall I find these models are getting good at following image as a source of instructions, but their refinement of the output varies heavily between the models. Astra's final output feels more polished, has better visual contrast, and the animations between the pages are smoother. Grok also chose to light all of the background elements, which imo overcooks it a bit.
Still though, for the price it's a great starting point.
For transparency, it took around 20M cache read + 1M input + 100k output tokens. API pricing for each:
Grok 4.7: $12.60
GPT Astra: $35.00
Not even close to astra. Astra is something else. It is expensive, but uses way fewer tokens do my tasks.
xAI missed its chance, Ball is on Anthropic's court.
Not surprising considering Grok 4.7 is a 2T model, so Sol/Opus class, not Astra/Fable class.
I don't understand these comments.
The two models are in completely different price tiers. Astra costs 5 times as much.
It seems like all you can judge about cars would be their maximum speed on an oval.
If you have a look at their headline benchmark on the post here, Grok 4.7 is hardly cheaper than Fable 5.1 Low and performs similarly.
Based on Artificial Analysis Cost per Task, Astra is about 2-3x cheaper than Fable 5.1 at Medium and Low.
Consequently Astra could be cheaper than Grok 4.7, depending on the task.
Astra fails in similar ways, and at similar frequency, as GPT 5.6 Sol does. It often goes way out of scope, or just stops prematurely, or tries to find odd and even dangerous workarounds when it gets stuck.
It's phenomenal at computer use and 3D stuff. I've been using it less and less for coding.
Same, Astra is extremely RL fried, and nobody is talking about it. I used Astra for a few days on my personal project, and load times went from less than 3 seconds to almost 30 seconds because it kept using the wrong sync primitives and bad architecture overall.
Huh, I've had a totally different experience. I've used it extensively, maxing out the 200€ plan on personal projects and it's the best model I've ever used, so easy and pleasant to use. It's great for frontend design and using it in Rust I've had Coming from Opus 5, it's a breath of fresh air.
I tried Astra w/ high reasoning on a design document project and it was horrible. It started duplicating output lines, made document edits without permission, and basically did a poor job writing clear prose. I went back to 5.6-sol and it's great. I'm an OpenAI fanboy and was severely disappointed. I hope Astra is better for coding.
No, Astra isn’t better for coding. I’ve switched back to Sol.
In programming I mostly use AI for Godot/GDScript code reviews, plus suggestions, and Astra is so much better than everything
Grok it's really expensive. I'm getting really amazing results using DeepSeek 4.1 Flash for fraction of the price.
Compared to the deep seek, gml sure but compared to OpenAI and Anthropic it’s actually very cheap.
In cursor I have switch over to grok for planning a composer for coding.
It’s a great value if you get Cursor Ultra. I basically have infinite tokens
What is the most secure way to use this model as someone who is lazy
I understand DeepSeek 4.1 Flash is available on US providers with Zero Data Retention if that is what you are asking.
Link for the lazy?
One example is Opencode. https://opencode.ai/v2/docs/console/models/
"Privacy# All these models are hosted in the US. Providers follow a zero-retention policy and do not use your data for model training, with the following exceptions:
Big Pickle: During its free period, collected data may be used to improve the model.
DeepSeek V4 Flash Free: During its free period, collected data may be used to improve the model.
MiMo-V2.5 Free: During its free period, collected data may be used to improve the model.
Laguna S 2.1 Free: During its free period, collected data may be used to improve the model.
Ling-3.0-tiny Free: During its free period, collected data may be used to improve the model.
LongCat-2.0 Free: During its free period, collected data may be used to improve the model.
North Mini Code Free: During its free period, collected data may be retained and used to improve the model. Do not submit personal or confidential data. See the provider’s Terms of Use and Privacy Policy.
Nemotron 3 Ultra Free (NVIDIA free endpoints): Trial use only — do not submit personal or confidential data. Your use is logged for security purposes and to improve NVIDIA products and services. The logged session data for improvement purposes is not linked to your identity or any persistent identifier. For more information about data processing practices, see the Privacy Policy. By interacting with this endpoint, you consent to the collection, recording, and use of such information and the NVIDIA API Trial Terms of Service."
openrouter, "together" provider is fastest (165 t/s at the time of writing) and has ZDR and all
https://openrouter.ai/deepseek/deepseek-v4.1-flash?endpoint=...
Sadly, there is no way to tell if this is running with real weights or being heavily quantized.
Eh, it's also one of the providers with "blind" vision models https://mmoustafa.com/blog/so-you-want-to-use-openrouter/
Yes, but with subpar caching and higher cached token pricing, compared to directly using the DeepSeek platform.
For caching, only if you don't specify your preferred providers and let OpenRouter route each request itself. I have stuff like this in my OpenCode config for each model I use and I regularly get ~90-95% cache hit rates.
    "order": ["relace", "coreweave", "novita", "baseten", "together"],
    "allow_fallbacks": false
But I can't argue with the lower off-peak pricing when using DeepSeek directly. The downside is they train their models on your input, which might be a deal-breaker for many users (as it is for me).
I use it on fireworks which is US/ZDR and pretty reliable. We run a few hundred million tokens/day through it for dollars. Many are cached, which is super duper cheap.
Brought to you by...
By no one. For the price of 1M token you can get more and with better results with other models.
Sure, if you're doing easy work. But Grok is a lot more intelligent and can handle harder tasks.
Define easy. I am running 40+ probes to crack the best compression algorithm, and I spent $3. If you surgically tackle the problems, you can do really complicated work for less money than by assuming a frontier top model will one-shot everything.
Well, at least I spent lots of dollars, and I had to use those models the same way I am using local and cheap models, with the same results.
DeepSeek 4.1 Flash is garbage, it almost only produced trash code. if you do extremely dumb things it is maybe sometimes fine to use.
Not only that all DeepSeek is all garbage.
GLM or Kimi are better for my own personal projects. DS? uhm. it just keeps doing dumb crap
No doubt xAI has seen rapid progress, but it's been several months of them being "just behind" OpenAI and Anthropic. It seems the gap between just behind the frontier and pushing it is a lot wider than most people thought it was a year ago, and that's why a clear third contender in the frontier model space has yet to materialize.
Looks like they have still problems with caching. Prize is double the other providers for cache hits... which is most of what I do. :/
Is Grok relevant? Who uses it?
Maybe I'm in some kind of bouble but I have never met or talked to anyone who has used Grok.
I use it in the car to talk to because it's built-in, mostly for navigation via voice. It seems to be an old or quantised model, because it seems a few years old, and it has strict rate limits unlike Gemini, where it really just shuts off if you talk to it a few times in one day, but it's still fun to show passengers who are still new to LLMs.
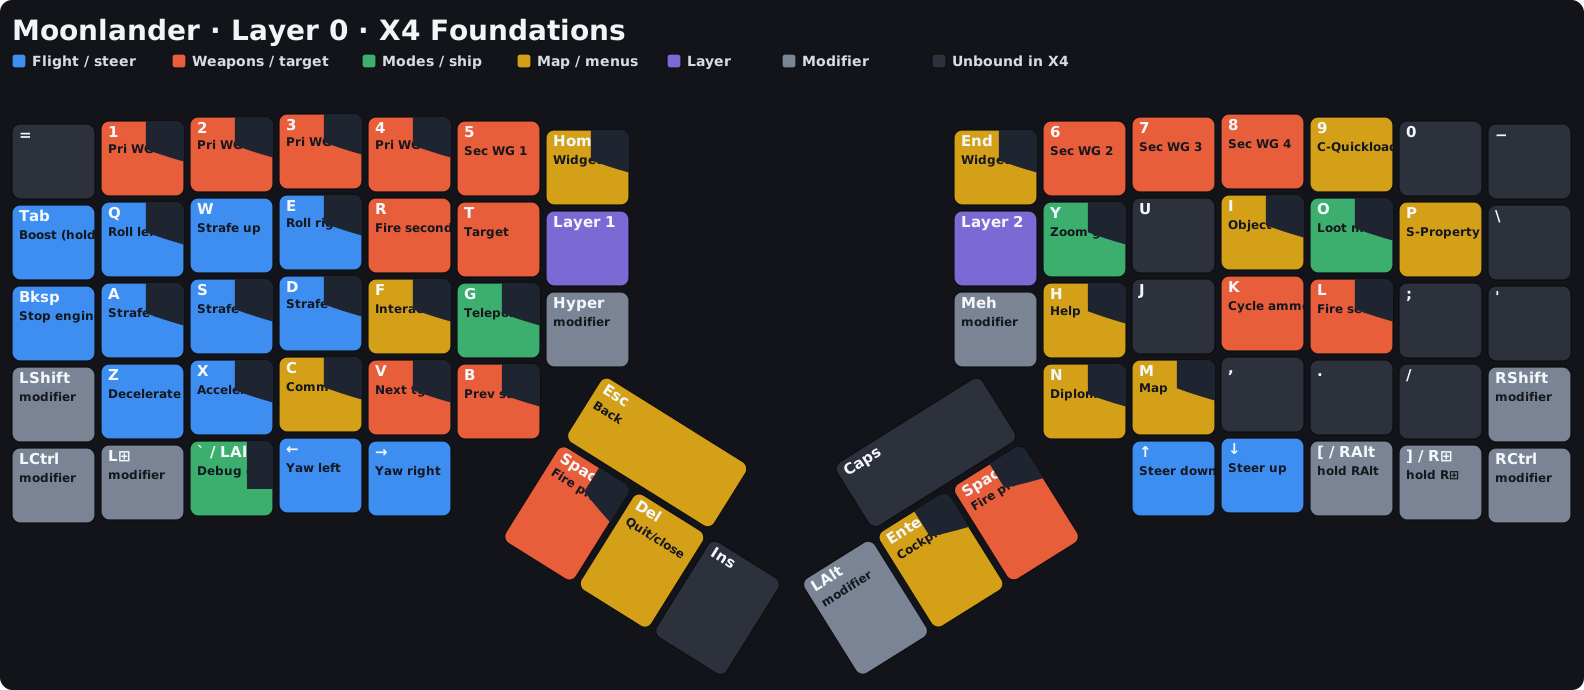
I've been using 4.6 for some one-off game mods/utilities and it has done very well. "I have a very niche keyboard (Moonlander) and I play this very niche space sim, make me a SVG keyboard cheatsheet for it". Told me to grab keymap.c for the keyboard and inputmap.xml for the game's key bindings, churned for a while, then spit out a pretty good first attempt, along with the python script used to generate it. Spent another hour of back and forth to refine the script, and now it generates great diagrams that will adapt as my keyboard firmware and game bindings evolve: https://files.catbox.moe/x0u76x.svg
Excited to try 4.7. I hope they fixed the "it's not X, it's Y" that showed up in 4.6.
Impressive! I had to peek at the SVG file and it superficially looks good, however, as is the case with everything AI, the more you look, the more it doesn't make any sense.
By now AI should know of the DRY concept. But no. Hence the keys have a rounded rectangle for the key shape and another rounded rectangle for a clip path, to prevent text overflow. There are 72 * 2 = 144 identical rectangles, when just one would suffice (in the defs), with this being cloned once for the clip path, and 72 times for the keys.
I would not expect SVGO levels of optimisation (rounding numbers, that sort of thing), however, the human, if writing out the same thing for the 72nd time, might think 'is there a better way', to get the manual out. A graphics program such as Illustrator would not do that, but AI 'should' because AI.
The above is not criticism of your work, just an observation regarding AI SVG capabilities.
Either way, the fact that xAI or SpaceXAI or whatever the name is, I can commend the team behind it on their rapid ascent and progress by being close and or on the frontier in several respects.
Your comment is like 6 months to a year late.
There for awhile it seemed like we’d have 3 big competitors but then Grok 4.2 or 4.4 was just diabolical while OAI and Claude continued their significant improvements. Grok was/is so bad that I was convinced musk was gonna shut it down and just fund Anthropic compute once they reached their compute agreement.
Good thing they used 5.6 sol instead of Astra for benchmarks, the EEbench one is crazy[1]
Significant regression in token efficiency compared to Grok 4.6 suggested by artificialanalysis.ai Intelligence Index Comparisons.
Output tokens from Intelligence Index:
- grok 4.6 (xhigh): 97M (for 44 score)
- grok 4.7 (xhigh): 240M (for 46 score)
Every Grok release obscures their cache pricing while highlighting their input/output pricing
From their headline comparison:
  Grok: $2/$6 per million

  Fable: $10/$50 per million


  What this doesn't say: Grok costs 0.50/M cache read, Fable $0.25/M cache read
Just makes Grok sound deceptive, and more importantly, reliant on user's lack of understanding of costs aka predatory (which in turn is more infuriating)
Does anyone have any experience with Grok's subscription? How does it compare price-wise to the API?
There are some users reporting it improved a lot in the last few weeks. The max sub usage for Grok is around $12,000 of API pricing now, so a 40x multiplier for the $300 plan.
It is the same multiplier for Sol with subscription. For Astra though the multiplier is ≈20x, so half of Sol usage.
For Claude it seems to be ≈40x too for Opus, but less for Fable (similar to Astra in GPT).
All on the most expensive plan. Previously, Grok usage escalated linearly from the $100 plan to $300 plan. That would be a really good $100 plan if it is still true.
Some sources:
1. https://x.com/kunchenguid/status/2098256018836963382
2. https://x.com/stevenzhang/status/2092110386569089311
3. https://github.com/openai/codex/issues/43731
I find I can just about get by with coding every day on a Cursor $60/mth sub with Grok fast mode disabled. Doing pretty heavy coding work/requirements etc, but not much sub agents and no loops.
For me and what I’m doing that’s insanely good value.
I find grok build chews through my SuperGrok sub very quick - but I think that is due to it having the 500k context window which uses more credits. Cursor limits it to 256K (tho I see in today’s update for Grok 4.7 there’s now a toggle for context size).
Well when I ran out of Grok SuperHeavy subscription ($300) once and tried to use extra credits to cover half a day remaining till reset, $50 in extra credits went in two hours. Based on that, subscription definitely lasts longer; Grok subscription just about covers a week of my work (sometimes a bit extra remains unused, sometimes it runs out half a day to a day early). And as a point of comparison, it lasts for doing same tasks as 2.5-3 weekly limits of Codex on 5.6 Sol did (using xhigh on both Sol and Grok); I needed 3x$200 Codex subscriptions to cover my weekly usage.
There are two ways to subscribe, and it’s very confusing, but the best value is to get cursor ultra for $200 a month. I basically have infinite tokens with that plan, plus grok bot, which I really like
By far the worst value subscription of any. I tried Superheavy and got about 5-10% the usage of CC/Codex.
Why Chinese models from Kimi, Deepseek are not added in comparison benchmarks?
Same reason Coca-Cola only mention Pepsi and Pepsi only mention Coca-Cola. It's an proven way to capture the market. You would rather split the pie in two rather than in 4,12 or 50 right?
Codex has become my goto tooling. I used to be a Claude Max subscriber, but I was becoming disappointed with the quality of the output from Opus 5. Fable chewed through my usage too quickly to be practical. Moving to a Pro account w/ Codex was a big improvement. Sol had great output, and the usage was more than sufficient for most of my needs. However astra does tend to chew up usage, so when i've done to much of that, and it's became an issue Grok Build has beocme my second go to account. The output especially after the cursor purhcase has become quite good, and the usage has always been very generous.
Try using astra as an orchestrator for deepseek 4.1 flash, it seems to work out quite well.
I am using exactly the same flow.
Astra for deep dive investigations, Sol 5.6 at mid-level for day to day tasks, Grok 4.6 via Cursor for routine and low complexity tasks.
after using cursor grok & trae.ai for several months , grok curor is highly superior results to trae.ai
Vals AI just affirm that Grok 4.7 is worse than Grok 4.6 (It ranks #24 on the Vals Index at 54.2%, down 5.0 points from Grok 4.6 (#14, 59.2%))
Is this an ad for Vals AI? Looking at their website, the rankings don't mesh with my observed utility for almost any model outside of fable and astra being good-ish.
Absolutely not. I know Elon retweet them a lot when Grok is good. This is how I discover the company.
I like to follow them and look for benchmark for each LLM release.
( why is the x-axis on the first chart in descending order ? )
as someone who is limited by amazon bedrock support at work (no idea why we got stuck with the worst one) - grok is literally the only budget-ish model option, so nice to see it updated, Sol and Opus are just too rich for my blood. Luna is good but so slow at getting things done (tps wise it's fast)
Are the prices on Bedrock substantially different to the rate cards of the direct APIs? Just trying to understand whether this is Opus-through-Bedrock is too expensive, or Opus is too expensive.
$2/million inout and $6/million output but I couldn't see any pricing information for cached input tokens?
cached input tokens are $0.50 per 1M (prompts under 200k tokens) and $1.00 per 1M (200k+)
the AA numbers are generationally bad. double token use (the one thing Grok was good at was low reasoning usage!) to gain 5% in the benchmark score. with reportedly a larger model. maybe it shows gains IRL but wow, I've never seen a new generation model look so underwhelming compared to the last.
looks like token efficient/verbosity took a big hit.
Output tokens from Intelligence Index:
- grok 4.6 (xhigh): 97M (for 44 score)
- grok 4.7 (xhigh): 240M (for 46 score)
which is crazy because this was grok's competitive advantage, worse than OpenAI models but better than everything else, now it's less efficient than Opus or Fable 5.1
32 on the omniscience index. Not terrible but far from Astra and fable: https://artificialanalysis.ai/evaluations/omniscience
Did 4.6 not have an x-high reasoning level? Why are they comparing 4.7 x-high with 4.6 high?
It did not. xhigh is new to grok.
Not sure on the API side, in Cursor you can always use 4.6 at xhigh.
We've only used it through API - but you're right, now API supports xhigh for 4.5-4.7.
I think 4.6 got an xhigh after launch. The benchmarks seem to all have been against 4.6 high.
In my experience Grok especially inside Grok build is pretty solid choice, it’s a no nonsense model and stays on its course. Another surface where I truly enjoy the experience of using Grok model is Grok bot
Yah, I am pleasantly surprised at Grok Bot. Hopefully this improves CUA which has been a touch lacking w/ Grok 4.6. Grok 4.6 works but is slow compared to stuff like Astra Light.
I've had really good experiences with Grok 4.6 and grok build. I've been playing around with tscircuit and it can write code with an understanding of spacial reasoning, while also importing cad components from different file formats into tsx, I've been having claude come in and try to error check it and so far claude hasn't found anything to improve in my three projects.
I'm excited for 4.7 although I share skepticism with other users whether 4.7 will be significantly better, since they didn't raise the price.
As anthropic/openai subscription allocations get squeezed you'll see more people using "second rate" closed models like grok. The token allowance with a Cursor subscription is crazy.
After mechahitler and understanding how it got to that point I am embarrassed for anyone who pays attention to or uses Grok. Do better.
It’s a shame this model has such negative political baggage associated with it. It’s the only one I decided not to run in my LLM benchmarks[1].
You'll have to include it in the future, or your benchmark won't be relevant.
For now, I doubt anyone would notice your protest if you didn't announce it.
I think you're seeing a big shift around it.... since it's been markedly cheaper and also still easily available from OpenCode, it's getting large enterprise traction.
Not sure why you are being downvoted. Until Musk owns up to his Nazi salute, I won't have anything to do with Grok, no matter how good or cheap it is. And yes, we need to keep talking about this because it's absurd.
Congratulations to the team!
SpaceX AI releasing "Grok" has to be some of the worst branding I've seen in my lifetime
xAI should offer persecuted White South Africans deep reverse-discrimination-victim discounts on Grok tokens.
Any real world experience with Grok Ultra $300 monthly subscription vs Claude Code Max in terms of overall built work mileage, or general token limits?
Yeah I switched and the 300 plan is basically introductory 100/ month and I never hit the limit. While constantly hammering on it
If the CursorBench 4.0 score diagram is the headline, I read it as "Grok 4.7 xHigh is almost the same as Fable5.1 on low".
Is there a metric for like... time taken when comparing these two? I see score and cost.
If Fable5.1 can knock it out more quickly on low but Grok4.7 might take twice as long to stumble through a problem (and leave behind a bunch of yucky comments or un-needed extra unit tests), are they really comparable?
Or like... the "quality" of the solution? "It works" versus "it's unmaintainable/very messy/hacky".
Pacing the frontier, with an aggressive release cadence. Gotta love the US tech industry.
What's with the deceptive graph on top? Not including Astra can't have been an oversight, did the model compare poorly to it?
https://openai.com/index/our-decision-on-cursor-following-it...
This explains why. Mentioned in another comment, but cursorbench explicitly tests with Cursor as the harness, and OpenAI doesn't allow them to use Astra in Cursor.
> with a proposed shutoff date of November 12, 2026
That said, I don't expect them to benchmark Astra in their Cursor harness given the situation.
Cursor never added Astra to its consumer subscription plans. And it's likely exactly because of this announcement. Why would they add support for a model they would have to remove shortly after?
shutoff for existing models, new models stopped as of that announcement, astra will never be on cursor.
That's not accurate. OpenAI doesn't allow Grok to provide Astra to Cursor customers anymore, but it doesn't ban anyone from using Astra via alternative harnesses.
If Cursor wanted to include Astra in CursorBench nothing would stop them, they could easily have spent half an hour vibecoding in OpenAI API key support - if it hadn't been convenient to neglect to do that.
If the benchmark is "what's the best model to use in your Cursor subscription", why would they do that? OpenAI knew what the effects of their decision were. Hard for me to have sympathy for either party here, honestly, and I say that as someone who is a customer of both.
Even if they could do that (workaround to include Astra in CursorBench), that has no practical consequences for Cursor users and that's what I as a Cursor user (what I use for dev, though I use ChatGPT for non-dev stuff) care about.
It would make the benchmark way better obviously, by showing how their new model compares to their competitors, the whole point of benchmarks and graphs.
The point of Cursor Bench is to show how models perform in Cursor. If 99% of their users won't be able to access a model unless they go out of their way to include setup an API key for it (which would be insanely expensive with Astra), why would they include it in the benchmark?
Deceptive? An extremely quick google search would answer your question. OpenAI pulled out of Cursor before they released Astra so it never got that benchmark.
Pulled out from letting them resell Astra access, that's not a limitation on running a benchmark.
I wonder if that means that SpaceX evals show that they consider astra better than fable or that they hate Sam&co so much they don't want to show their stuff.
https://openai.com/index/our-decision-on-cursor-following-it...
Its because of this. You can't use Astra in Cursor, and cursorbench uses cursor as the harness. They can't actually benchmark it using their harness hence why its not included.
They have Astra in other benchmarks lower on the page. They just don't want to show it winning
The chart is cursorbench though and they asked about the "deceptive graph"
They can benchmark it because you can use an openai api key with cursor. Astra is just not included in the cursor plan.
Elon posted on X that Grok 4.7 is behind Claude and OpenAI for agentic coding:
https://x.com/elonmusk/status/2102082011233931762?s=20
so it's likely about usage in Cursor specifically.
Dumb question. Are these products really winner-take-all? Why is there such a furious rate of development?
It’s not at all winner takes all, it’s a race to the bottom. Models are becoming a commodity
because boomers will give you free money + tip
musk can fund the space stuff with this
I tried in Omp (Oh-my-pi), and so far it's really problematic.
It will loop in thinking mode ("Let me implement those fixes: Fix 1, Fix 2, Fix 3 .... Fix 80, Fix 81"), ignore the AGENTS.md instructions, corrupt plan files, etc etc... I have 5.6 Sol as advisor/watchdog, and it blocks every turn, I never saw this. Quite a shame, 4.6 wasn't so bad.
OMP is a joke. don't use that garbage
Can you explain your opinion? I'm curious but such vague comments won't convince me.
Probably the same reason as oh-my-zsh, you don't need 90% of it. Further compounding the problem in an agent harness is that you are polluting the context window by throwing the kitchen sink at it.
I've been experimenting with omp because:
- it allows different models within one session via roles (I only have API, so pay per token)
- it's much more likely (ime) to use the LSP over grep for determining how code fits together
But I agree a 20k+ starting context is way overkill.
I find it's very hard to get information on harnesses people are using. I have to stay model agnostic so I avoid claude, codex, cursor, etc. I've used and tried opencode, which worked well, but obviously lacks the above features.
Does anyone have a resource for following what people are actually being productive with? With so much vibe going on it's hard to separate the wheat from the chaff.
this summarizes the average OMP user and dev
Again, this is vagueposting, what do you have against snapcompaction? It seems to be a nifty way to save token costs. At least it's an interesting innovation. https://x.com/_can1357/article/2064802476742574459?lang=en
What a crazy thread lol. I really can't tell who is serious and who isn't there.
what do you use and why do you prefer it over omp
Just pi. `pi install` the packages you actually need or ask LLM to write a package for you. Keeping the harness minimal is the point of pi.
I guess it’s only my opinion but having used grok for personal chat: it’s by far the worst one amongst Claude, ChatGPT and even Deepseek, Gemini etc.
The personality is bland and it doesn’t work nearly as hard or even tries to help.
> The personality is bland
I don't use Grok, but do you want your LLM to have a personality? "Personality" is exactly what people don't like about Claude.
I want my sexbot to have a personality
What if it doesn't like you
Sexbots respond surprisingly well to abuse.
longdong1
created: 9 minutes ago
That could have been said just as perfectly well from a main account my guy/guyette
This has been my experience as well. Grok will end tasks almost immediately and claim "Done!". It's definitely the laziest and most "dishonest" of all the models. The others aren't perfect, but I can't use Grok for any serious coding task.
I used openrouter to send same prompt to qwen, derpseek, gemini and grok and found that grok does good research and produces less bullshit, especially when prompted to be critical of an idea
Ask it to be critical of the birthday photos and see where that gets you.
can you elaborate?
As stated by another comment Elon Musk's mother posted an AI-edited photo marked as such. It got edited right away to remove that label.
There are ample reasons to believe that Elon Musk is running his mother's account and that the photos weren't even real putting in question that he even had a birthday party.
If you ask Grok about what this means it will always take Elon's defence. It will vehemently deny that Elon would be capable or willing participant of such a thing even if you point out that he faked being a world class gamer, buying accounts that had done all the work and showing none of the skills when live-streaming.
Elon's mother recently posted an AI-generated photo of her son's birthday party. The tag indicating such was scrubbed as soon as it was pointed out.
> The personality is bland
Sounds like a plus. Guess I will give Grok another try...
> it doesn’t work nearly as hard
Until you ask it to start generating horrific imagery and then it's best in class.
I would consider this a positive. I'm not interested in a company that wants to prevent you from using a tool that you're paying for.
The value of the internet is that people can share whatever they want, and use software how they want. This will mean that some people will abuse that. This is the tradeoff of a free society.
Until Musk owns up to his Nazi salute, I won't be using Grok, sorry. I don't care how good or cheap it is. And no, I won't stop talking about it either.
There is no need to use it anyway, it's always been uninteresting in terms of performance. However, for me the red flag was when Musk admitted he will personally interfere in its training and prompts to make it more of a propaganda tool. I'm interested in science and reality, not in the political delusions of elderly drug addicts.
And poisoning Memphis. So disappointing that no one has principles anymore
[dead]
[dead]
Waiting on simonw "Generate an SVG of a pelican riding a bicycle " benchmark to judge this model
It might be more capable, but AA indicates it's a lot less token efficient than Grok 4.6: https://artificialanalysis.ai/agents/coding-agents?agents=co...
[flagged]
You don't think it's useful to learn whether a model's "intelligence" generalizes beyond the tasks and modalities it is usually optimized for?
Absolutely not. Makes about as much sense as judging a car based on how good an airplane it makes.
Have you considered that the single most impressive breakthrough of LLMs as a technology is their ability to generalize beyond what they were explicitly trained on? Great analogy, pal, but LLMs aren't cars.
I disagree. If GPT-7 can draw the Mona Lisa in MS Paint via computer use, this would be interesting.
That it isn't the most efficient way to achieve the same end result is irrelevant.
[dead]
[flagged]
Everyone should be clear that this is what they’re cheering on when they celebrate a Grok performance win. A technology is no longer neutral when wielded by a self-proclaimed white supremacist whose actions have killed over a million black and brown people, mostly children and babies.
Exactly. And it's DEEPLY DISTURBING that all comments on HN that point out that X is pro-nazi no longer has an upvote button
[flagged]
[flagged]
Thank you for your perspective and I agree as repetitive as it is, I hope hn can continue to surface disagreement/substantial views on a topic.
These comments don't stay up much anymore and I can't tell if it's structural to the forum (flag weight + statistical mechanics of votes + guidelines) or if it's the userbase sentiment.
Except for now HN doesn't do that. Every single comment that points the issue with Grok being built by a pro-fascist team is being "locked" so that they can't be upvoted
For what it's worth, I've watched the vote fight on my comment swing back and fourth over the last hour. It got flagged, unflagged, and flagged again. It appears to now be locked and dead.
But I think it represents real malaise in the community. It's not a moderator plot, people here really just don't care and might even support this.
We really are in the minority of opinion for giving a damn about liberal democracy.
I think I was trying to bring up the mechanics of the forum as another reason.
Between the guidelines + user thoughts (e.g. repetition, low novelty/new info), there's other reasons these types of replies might end up dead.
I am worried that it leads to people self selecting to other forums biasing the remaining userbase vote/vouch/flag distributions. In an exit vs voice situation, the voice kinda dies out. Then we end up other-izing people and homogenizing our communities.
But I concede it's also possible that the minority opinion issue could be the core driving force.
Yeah, not touching xAI for several glaring reasons. I share your confusion.
I completely agree. But this has been true for many years. This sort of head in the sand compartmentalization seems to be a core feature of the culture here.
Definitely not a musk fan, but what exact is your point? Other big labs aren't innocent little virgins.
Yes, but the other ones we don't like for ethical reasons, rather than religious reasons.
I think I already made my point, but I'll make it again.
Nobody both worked and spent their money to get Trump elected like Musk. 300 million to his 2024 campaign [1]. DOGE. On-stage endorsements. Nobody even came close.
No, other big labs are not "innocent little virgins", but they're not even in the same solar system of harm as Musk. To hand-wave at the differences is to permit them.
[1] https://www.opensecrets.org/2024-presidential-race/donald-tr...
[flagged]
Musk is literally burning methane for funsies, and generating CSAM and getting sued for it.
Handing corporate code secrets to his AI model is... unusually trusting.
How many years will go by before people will stop talking about the CSAM thing that happened for only a few days as if its still happening? FWIW, it's bad it was generated, but equating it to harming of real children I think is not a good thing.
And methane is a large percentage of all power production in the US. So again that also applies to all the other data centers. (And FWIW they've been winding down and shutting down the on site methane generators.)
And no corporate code was handed to AI models.
It’s not just that it was generated, it’s that they argued in court, _and won_, that it was legal, giving every last predator a nigh-on unverifiable defence.
I have to say grok, grok, grok, grok, grok. Also, anyone who doesn't modulate across models and run their own memory system is an idiot.
[flagged]
Judging by Elon's staggering success in all of his ventures I'd say you're out of touch.
Multiple things can be true at once, he can be wildly successful while also undermining democracy.
Think we all can agree he has had staggering successes, but they have all come from having massive capital from Paypal which wasn't anything super innovative, it just solved a convenient problem at a convenient time and was awarded handsomely. Elon has put his capital to work in various ways to become successful, not all of the ways being morally sound.
All except Starlink and Tesla are burning money. I personally don't consider that "staggering success."
He has had many failures, SolarCity and xAI and X and DOGE to name a few, but he has often bailed them out with his larger ventures.
Even with his successes (Tesla, SpaceX) he has built them up in large part by bending levers of government to his advantage.
I take issue with your use of the word "bend" here.
Can you provide specific examples of where Elon has bent the levers of government?
> Even with his successes (Tesla, SpaceX) he has built them up in large part by bending levers of government to his advantage.
So what? Thats called being a maverick. He is very very good at executing on making money which is the point of business.
> He is very very good at executing on making money which is the point of business.
Also pushing technology forward.
xAI is the most profitable part of SpaceX by far.
About half of SpaceX revenue is Starlink subscriptions. Starlink is the one profitable division; the rest of the company operates at a loss, including xAI.
That's outdated and doesn't fully include the multiple billion per month contracts.
Anthropic: 1.25B/month
Google: 0.92B/month
Unnamed customer starting in december: 1.1B/month
Starlink monthly revenue is ~1.5B/month
Isn't this to rent the datacenters though? That's not really long term revenue if xAI will eventually need them back.
Renting datacenters is their mission, now on earth and later in space (assuming they deliver).
What failed with X? Usage today is higher than ever
Brand reputation; ROI; grok the sexual harassment bot; grok the CSAM bot; his free speech absolutism position. Take your pick.
Hardly seems worse than supporting Dario’s antics at least vis a vis AI. There are no saints in this industry, only a panoply of flawed humans.
The public very much voted for massive administrative reform. Are you refering to DOGE, Elon Musk's influence on elections, something else?
I personally don't like him using his position to spread fake news and racist propaganda
As if "the public" knows literally anything about how the US federal government is administered.
If anything, they voted for reduced debt burden and they got the opposite. DOGE failed at pretty much every single one of the goals that the public arguably gave it a mandate for.
> As if "the public" knows literally anything
Ah, yes, democracy!, except for when the public is wrong.
Who decides when the public is wrong? We do! Who decides "what the public voted for"? We do! So we are the rulers? No, of course, not, this is democracy.
You want to become the decider of when the public is wrong and of what the public voted for? TYRANT! TYRANT!
No, the claim above is "I know the voters' intent behind their vote based on who they voted for."
This is simply epistemologically incorrect. It's obviously incorrect in this case because voters writ large do not have any idea how the government is administered and how to improve it, so even if they claimed to be voting for that, it would not necessarily be an endorsement of any particular approach.
More specifically we know it's not true in this case because there are polls. Voters didn't even claim to care about this! "How the government is administered" was not a high salience issue to voters. Simple as that.
Nonetheless, I didn't suggest anything about overriding their votes. It sounds like you have some sensitive spots to work through (someone obliquely criticizing your idol for sucking at his job?)
being ignorant and influenced is different from being wrong, the american electorate is well known to be under informed
half of voters don't pay any attention to politics until the week or two before voting
[flagged]
[flagged]
Only sheep call other people sheep.
Sheep often like to think themselves the wolf or coyote, it would seem.
Holy shit, what his whole speech. Yes go watch it. There is zero way. Zero it wasn’t a Nazi salute.
Fuck, it is like the denial around Jan 6th. Those idiots we’re live streaming that shit. I watched it go down live. Now they say they weren’t violent.
We can’t have discourse when we have legit video evidence and people refuse to open their eyes and choose to deny reality
Why would he make a Nazi salute and then shit all over Nazi ideology?
Which Nazi ideologies do you think he embraces? How do you reconcile all the Nazi ideologies he rejects?
"Hey bro, you have a lot of money but bet you can't do a nazi salute on live television"
"You're on, bro"
When did he "shit over nazi ideology"? He mentioned multiple times he favors white supremacy, and hates "empathy", how many more clues do you need?
Weird, that's the main reason I purchase all of Elon's products https://time.com/5936036/secret-2020-election-campaign/
[flagged]
Try it for software development.
I have even less trust in their not training on my data/credentials/everything on my computer.
Seriously. They already get caught uploading everyone’s private credentials once before, one would have to be a particularly gullible rube to trust grok again. Especially with musk in charge.
This thing is DOA. They compared 4.7 xhigh to 4.6 high to make it look like it improved. The reality is pretty bad: https://x.com/chetaslua/status/2102087511367618942
I refuse to use Grok. Mostly because of the usual reasons - somehow this high profile AI model seems more disgusting than others and it is in a way impressive.
But also Xai doesn’t seem to care about user experience and long term support.
I am subscribed to ChatGPT, Claude, Kimi and GLM coding plans. 200$ one on GPT and the 20$ ish ones on all others. Recently added Grok and it has somehow bacome my second most used model.
For daily one off questions I prefer it because it is fast enough and I like the way it responds. I also use it for basic research like “find me a battery drill for this and that”.
Kimi and GLM feel extremely coding oriented. I use them for code reviews basically. I hate the way Anthropic models talk. GPT takes too much time and effort for that kind of stuff for some reason.
Grok happened to be a nice middle ground.
I can't take anyone seriously who uses grok seriously. I like to look at the cybertruck owners forum every so often because it's just... hilarious. And the amount of superfluous grok use over there is just insane. Half the posts I click in there will have a bunch of people dumping entire grok takes "why do people hate cybertruck owners?" "Because they're jealous and poor," sort of stuff that they just LOVE to post.
As a technical point of reference to compare against other llm stuff, sure, I'll glance at a report or benchmark but I really couldn't care less about anything to do with the project and it could blow other options away and I wouldn't touch it.
Possibly interestingly, I can't take you seriously for having such a superficial approach.
You probably shouldn't cut off your nose to spite your face.
I don't know man, Musk doing Nazi salutes doesn't seem that superficial. He did help get Trump in power and also killed a lot of aid to children that need it.
What's superficial about refusing to use a product from someone like that? Or are you one of those 'technology isn't about politics' people? That's a superficial take if you ask me.
All technology is political, and understanding that is a deep, not superficial take. It requires systems thinking which unfortunately many people building technology seem to lack, despite software being a sophisticated complex system.
You should try it, it is less sycophantic than other models and is faster and better at most reasoning levels, don't confuse the twitter bots and services also named Grok with the frontier model itself
Who uses this trash?
Well I "tried it out" I asked it one question, and it gave no answer and said "Sign up to use more!" I don't think I'll be doing that, no.
I can't think of a single dimension grok is winning on (capability, cost, voice), but want to stay open-minded -- anybody want to vouch for its capabilities in any domain?
If you haven't used it, how do you know if it's winning?
I think it's winning on UI for normies (grok bot) and they made some claims about being pareto SOTA (lowest cost per task completed) a while back with 4.6.
I find it to be a perfectly capable model for implementation (there are many in this class--deepseek flash, spark1.3, luna, etc). I find the usage to be very generous w/ supergrok. I find the model to be just fine for 90% of what I want to do, but I use a smarter model to plan complicated things.
After the cursor aquisition it's become a quite capable coding model. If you take cost into account, it's close to the top. OpenAI is maybe still #1, but I'd put Grok at #2 (again, including cost as a factor).
For me it works well for agentic coding tasks and terminal/unix/bash (in cursor and grok build); it's also token efficient and cheaper than gpt 5.6. It's def not as good as Fable for me (I haven't used Astra much, can't comment). So it's not the cheapest, not the most capable, but it has a good mix of it for my backend, go, infra work.
The voice is the same AI slop as the others imho.
(This is about Grok 4.6, I didn't test 4.7 yet).
edit: clarified I mean agentic coding tasks
The voice is the weird part. The early Grok 4 models had a very distinct presentation unlike anything else out there. Then suddenly it made a big jump in coding ability and started sounding just like every other model.